Machine Learning Engineer (MLE) Resume Examples & Free PDF Template

A free Machine Learning Engineer resume template from a tech resume writer. Fill in the highlighted fields, change anything you like, and download the PDF.

4.9 5.0
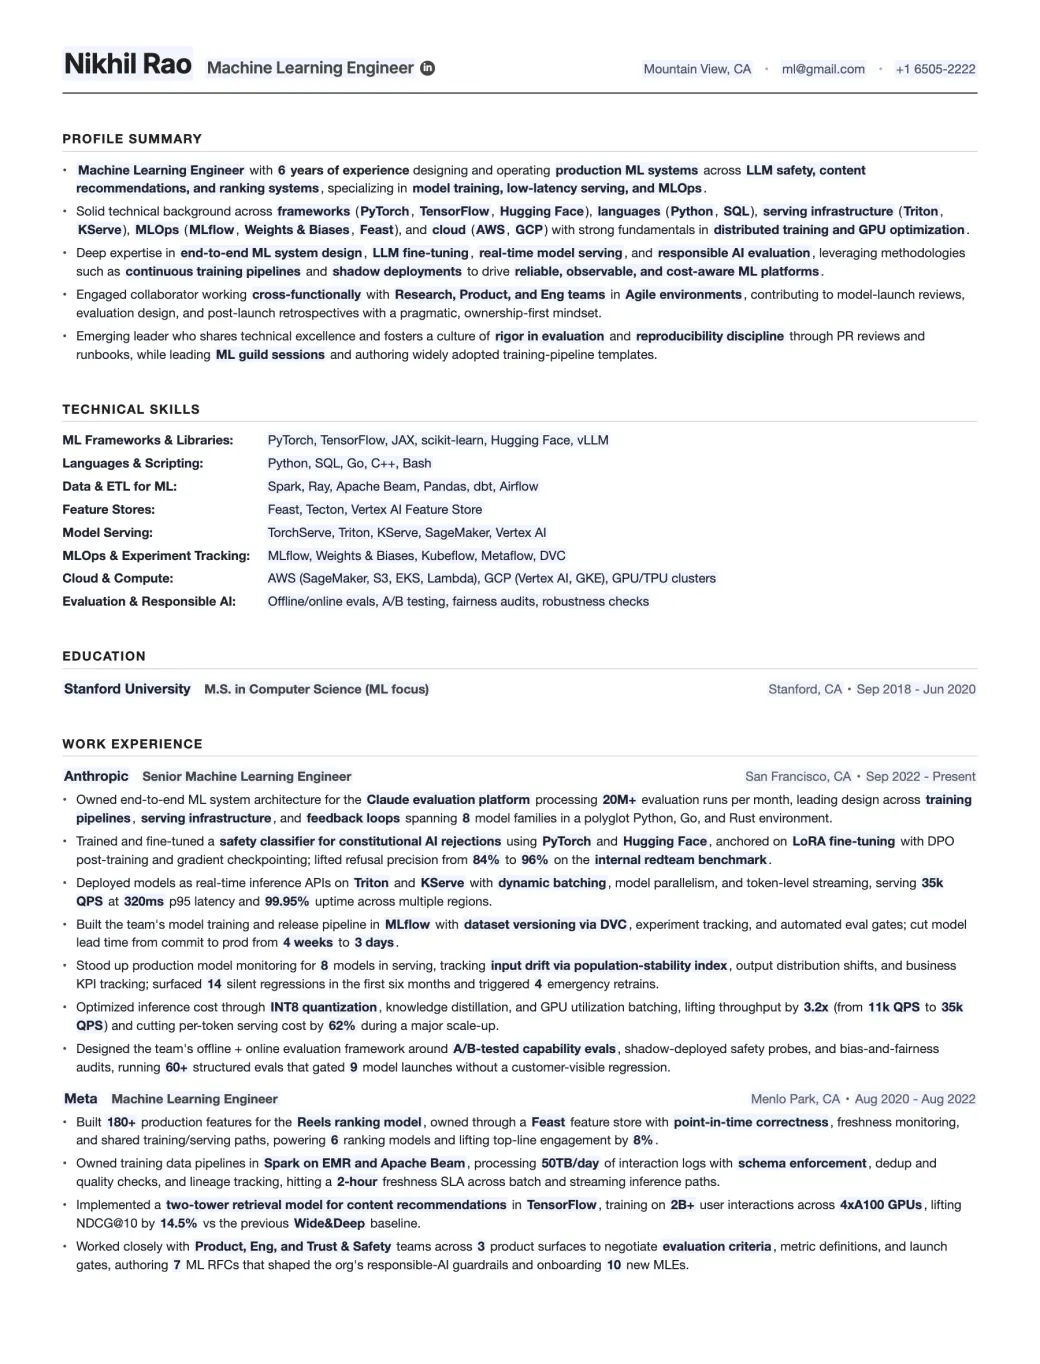
The Machine Learning Engineer resume template, filled in: profile summary, technical skills, education and work experience with the editable placeholders highlighted
Emmanuel Gendre Ex-Google recruiter / Tech resume writer Updated September 15, 2026 Free, ATS-friendly, no signup

Interactive resume template generator

Interactive ML Engineer Resume Template

Edit the side panel. The resume rewrites itself live. Save as PDF when you're done.

Edits update live as you type. Toggle Edit to rewrite paper text directly.

Edit mode is on. Click anywhere on the resume to rewrite text. Side-panel placeholders still update live.

Nikhil Rao Machine Learning Engineer

Mountain View, CA ml@gmail.com +1 6505-2222

Profile Summary

  • Machine Learning Engineer with 6 years of experience designing and operating production ML systems across LLM safety, content recommendations, and ranking systems, specializing in model training, low-latency serving, and MLOps.
  • Solid technical background across frameworks (PyTorch, TensorFlow, Hugging Face), languages (Python, SQL), serving infrastructure (Triton, KServe), MLOps (MLflow, Weights & Biases, Feast), and cloud (AWS, GCP) with strong fundamentals in distributed training and GPU optimization.
  • Deep expertise in end-to-end ML system design, LLM fine-tuning, real-time model serving, and responsible AI evaluation, leveraging methodologies such as continuous training pipelines and shadow deployments to drive reliable, observable, and cost-aware ML platforms.
  • Engaged collaborator working cross-functionally with Research, Product, and Eng teams in Agile environments, contributing to model-launch reviews, evaluation design, and post-launch retrospectives with a pragmatic, ownership-first mindset.
  • Emerging leader who shares technical excellence and fosters a culture of rigor in evaluation and reproducibility discipline through PR reviews and runbooks, while leading ML guild sessions and authoring widely adopted training-pipeline templates.

Technical Skills

ML Frameworks & Libraries:
PyTorch, TensorFlow, JAX, scikit-learn, Hugging Face, vLLM
Languages & Scripting:
Python, SQL, Go, C++, Bash
Data & ETL for ML:
Spark, Ray, Apache Beam, Pandas, dbt, Airflow
Feature Stores:
Feast, Tecton, Vertex AI Feature Store
Model Serving:
TorchServe, Triton, KServe, SageMaker, Vertex AI
MLOps & Experiment Tracking:
MLflow, Weights & Biases, Kubeflow, Metaflow, DVC
Cloud & Compute:
AWS (SageMaker, S3, EKS, Lambda), GCP (Vertex AI, GKE), GPU/TPU clusters
Evaluation & Responsible AI:
Offline/online evals, A/B testing, fairness audits, robustness checks

Education

Stanford University M.S. in Computer Science (ML focus)
Stanford, CA Sep 2018 - Jun 2020

Work Experience

Anthropic Senior Machine Learning Engineer
San Francisco, CA Sep 2022 - Present
  • Owned end-to-end ML system architecture for the Claude evaluation platform processing 20M+ evaluation runs per month, leading design across training pipelines, serving infrastructure, and feedback loops spanning 8 model families in a polyglot Python, Go, and Rust environment.
  • Trained and fine-tuned a safety classifier for constitutional AI rejections using PyTorch and Hugging Face, anchored on LoRA fine-tuning with DPO post-training and gradient checkpointing; lifted refusal precision from 84% to 96% on the internal redteam benchmark.
  • Deployed models as real-time inference APIs on Triton and KServe with dynamic batching, model parallelism, and token-level streaming, serving 35k QPS at 320ms p95 latency and 99.95% uptime across multiple regions.
  • Built the team's model training and release pipeline in MLflow with dataset versioning via DVC, experiment tracking, and automated eval gates; cut model lead time from commit to prod from 4 weeks to 3 days.
  • Stood up production model monitoring for 8 models in serving, tracking input drift via population-stability index, output distribution shifts, and business KPI tracking; surfaced 14 silent regressions in the first six months and triggered 4 emergency retrains.
  • Optimized inference cost through INT8 quantization, knowledge distillation, and GPU utilization batching, lifting throughput by 3.2x (from 11k QPS to 35k QPS) and cutting per-token serving cost by 62% during a major scale-up.
  • Designed the team's offline + online evaluation framework around A/B-tested capability evals, shadow-deployed safety probes, and bias-and-fairness audits, running 60+ structured evals that gated 9 model launches without a customer-visible regression.
Meta Machine Learning Engineer
Menlo Park, CA Aug 2020 - Aug 2022
  • Built 180+ production features for the Reels ranking model, owned through a Feast feature store with point-in-time correctness, freshness monitoring, and shared training/serving paths, powering 6 ranking models and lifting top-line engagement by 8%.
  • Owned training data pipelines in Spark on EMR and Apache Beam, processing 50TB/day of interaction logs with schema enforcement, dedup and quality checks, and lineage tracking, hitting a 2-hour freshness SLA across batch and streaming inference paths.
  • Implemented a two-tower retrieval model for content recommendations in TensorFlow, training on 2B+ user interactions across 4xA100 GPUs, lifting NDCG@10 by 14.5% vs the previous Wide&Deep baseline.
  • Worked closely with Product, Eng, and Trust & Safety teams across 3 product surfaces to negotiate evaluation criteria, metric definitions, and launch gates, authoring 7 ML RFCs that shaped the org's responsible-AI guardrails and onboarding 10 new MLEs.

Done editing? Download as a real, vector PDF. Selectable text, ATS-friendly, US Letter format.

About this template

A Machine Learning Engineer Resume Template, written by a tech recruiter.

$185,751 Average advertised base salary for US ML Engineers Indeed, 5.2k job postings

Machine Learning Engineer is the fastest-growing job in the US right now. LinkedIn’s Jobs on the Rise 2026 report puts AI engineer (their name for the MLE role) at number one, and the most requested skills on those postings are LangChain, RAG and PyTorch. That tells you where the job went: five years ago an MLE trained models, and today most of the work is fine-tuning, retrieval, evals, and getting inference to run fast and cheap.

What recruiters check on an MLE resume is fairly specific: models shipped to production (not notebooks), the training and serving stack you actually ran, evaluation (offline metrics, A/B tests, LLM evals), and numbers that moved: accuracy, latency, throughput, GPU cost. Newer postings add LLM work on top: fine-tuning, RAG pipelines, and inference optimization with vLLM or TensorRT-LLM.

I built the template on this page around exactly those expectations, so you cover what hiring managers want to see in 2026 without listing every library you have ever imported.

Keep scrolling for three complete MLE resumes (junior, senior and staff) and a section by section walkthrough with the reasoning behind each part of the template.

Already have a resume and want to know how it holds up? Send it over for a free review.

Resume Sample

Machine Learning Engineer Resume Examples

Not sure how much an MLE resume should change with seniority? I wrote 3 of them: a junior, a senior and a staff Machine Learning Engineer, and each one is a free PDF download.

Junior ML Engineer Resume Example

Years of experience
2 years
Industry
Foundation models
Stack
PythonPyTorchHugging FaceFastAPI
Download as PDF

Click to download the Junior ML Engineer resume example as a PDF. Free / No signup.

Diego Velasquez

Junior ML Engineer

Toronto, ON · diego.velasquez@gmail.com · +1 416-555-0137 · linkedin.com/in/diegovelasquez

Profile Summary
  • Junior ML Engineer with 2 years moving research prototypes into production at a foundation-model lab, across retrieval and reranking models, specializing in fine-tuning pipelines, retrieval evaluation, and reproducible experiments.
  • Hands-on across primary language (Python), training framework (PyTorch and PyTorch Lightning), model hub (Hugging Face Transformers), experiment tracking (Weights & Biases), serving (FastAPI), and containers (Docker), with working knowledge of Ray and AWS SageMaker.
  • Growing expertise in embedding-model fine-tuning, retrieval evaluation (recall@k, MRR, nDCG), and data preprocessing tests, using versioned datasets and weekly eval reviews to keep every training run reproducible from a commit hash.
  • Works day to day with research scientists, senior MLEs, and the platform team under senior mentorship, joining paper reading groups, eval reviews, and release checks for 2 training pipelines and 3 evaluation pipelines.
  • MSc thesis on dense retrieval for long-context QA built the useful half of the job: can read a new paper on Monday and have a faithful baseline running by Friday, with the eval harness to prove it.
Technical Skills
Languages:
Python, SQL, Bash, Git
Deep Learning:
PyTorch, PyTorch Lightning, Hugging Face Transformers, Hugging Face Datasets, embedding models
Fine-Tuning:
LoRA and full fine-tuning of embedding and reranker models, mixed precision, checkpointing
Evaluation:
recall@k, MRR, nDCG, eval harness jobs, pytest for preprocessing, model cards
Data & Tracking:
pandas, NumPy, Weights & Biases, DVC (basics), versioned datasets
Serving & Infra:
FastAPI, Docker, AWS S3, AWS SageMaker (basics), Ray (basics)
LLM Tooling:
RAG pipelines, tokenizers, prompt and eval datasets, LangChain (basics)

Diego Velasquez

Page 2 of 2
Work Experience
Cohere Junior ML Engineer Toronto, ON · Sep 2023 - Present
  • Built and maintain 2 fine-tuning pipelines in PyTorch Lightning for retrieval embedding models, covering data loaders, checkpointing, and Weights & Biases logging, so a run restarts from any checkpoint in under 5 minutes.
  • Own the recall@k and nDCG dashboards for retrieval and reranker models inside the internal eval harness, adding 6 evaluation jobs that 2 senior MLEs review every week before a release.
  • Helped build 3 retrieval evaluation pipelines on Hugging Face Datasets for long-context QA, multilingual recall, and citation grounding, growing the eval set from 4k to 31k labelled queries.
  • Wrote pytest suites for data preprocessing across 4 tokenization paths, catching 2 silent encoding bugs before they reached a training run and adding the checks to CI.
  • Automated model-card generation from training metadata in Python under senior review, cutting per-release prep from 4 hours to under 30 minutes.
Layer 6 AI Research Intern, then Junior ML Engineer Toronto, ON · Jun 2022 - Aug 2023
  • Reproduced 4 published sequential recommendation baselines in PyTorch, including data loaders, training loops, and offline evaluation on MovieLens-25M and proprietary banking sequences.
  • Built a scikit-learn baseline harness that 3 research scientists ran as a sanity check before every deep-learning experiment, saving a day of GPU time per failed idea.
  • Wrapped a transformer reranker in a FastAPI endpoint with input validation, packaged it in Docker, and deployed it to a staging EKS cluster for the product team to try.
Education
University of Toronto M.Sc. in Computer Science Toronto, ON · Sep 2020 - Jun 2022
University of British Columbia B.Sc. in Computer Science Vancouver, BC · Sep 2016 - May 2020

Senior ML Engineer Resume Example

Years of experience
7 years
Industry
Consumer gaming
Stack
PythonPyTorchRaySpark
Download as PDF

Click to download the Senior ML Engineer resume example as a PDF. Free / No signup.

Naomi Tanaka

Senior ML Engineer

San Mateo, CA · naomi.tanaka@gmail.com · +1 650-555-0164 · linkedin.com/in/naomitanaka

Profile Summary
  • Senior ML Engineer with 7 years building recommendation and ranking systems at consumer gaming and AR scale, specializing in candidate generation, two-tower retrieval, and online experimentation.
  • Hands-on across primary language (Python), training framework (PyTorch), distributed compute (Ray and Spark), vector search (FAISS and ScaNN), ML platform (Vertex AI and MLflow), and feature store (Feast), with strong fundamentals in two-tower and DLRM architectures.
  • Deep expertise in candidate generation, online A/B test design, and training-serving skew prevention, using methodologies such as CUPED variance reduction and holdout audits to ship models whose offline gains survive the online test.
  • Owns 3 production models end to end with Product, Backend, and Data Platform teams, from training pipeline and offline eval to online rollout, monitoring, and the on-call rotation for the homepage candidate generator.
  • Emerging tech lead who mentors 3 mid-level engineers and runs the weekly experiment-review forum, with 4 RFCs adopted by the recommendations platform team, including the feature-store rollout.
Technical Skills
Languages:
Python, SQL, Go (services), Bash, C++ (basics)
Deep Learning:
PyTorch, JAX, Hugging Face Transformers, two-tower and DLRM models, sequence models
Retrieval & Ranking:
FAISS, ScaNN, candidate generation, hybrid retrieval, learning to rank, ranking pipelines
Distributed & Data:
Ray, Spark, Dataflow, Beam, BigQuery, Parquet, Feast feature store
ML Platform:
Vertex AI, Kubeflow Pipelines, MLflow, GitHub Actions, model registry, batch and online inference
Experimentation:
online A/B test design, CUPED, sequential testing, multi-armed bandits, holdout audits
Observability:
Prometheus, Grafana, model-drift monitoring, training-serving skew alerts, gRPC serving

Naomi Tanaka

Page 2 of 2
Work Experience
Roblox Senior ML Engineer San Mateo, CA · Aug 2022 - Present
  • Own the homepage candidate-generation model, a two-tower retrieval system over 40M+ experiences for 70M+ daily active users, with full responsibility for training, evaluation, rollout, and on-call.
  • Rewrote retrieval from a legacy matrix-factorization baseline to a two-tower model in PyTorch on Ray, lifting session relevance by 32% and homepage CTR by 11% in a 4-week A/B test.
  • Built a FAISS and ScaNN hybrid retrieval layer behind a gRPC service, serving 18k QPS at p99 under 35 ms with index refreshes every 30 minutes.
  • Cut training-serving skew incidents from 8 per quarter to 1 by adding training-time feature snapshots in Feast and a feature-consistency check in CI.
  • Design and ship 10 online experiments a quarter with Product, including 3 holdout audits, using CUPED to cut the time to a significant read by roughly a third.
Niantic ML Engineer San Francisco, CA · Jul 2018 - Jul 2022
  • Shipped 5 ranking models for the Pokémon GO sponsored-location surface, owning training pipelines on Kubeflow Pipelines with MLflow tracking, and 22 A/B tests behind a 14% revenue lift.
  • Owned the player-segmentation feature pipeline on Spark and BigQuery, processing 4B+ events a day for 12 downstream consumers with freshness alerts in Grafana.
  • Migrated 3 legacy TensorFlow models to PyTorch, cutting training time by 40% and unblocking the team's move to Ray distributed training.
Education
University of California, Los Angeles B.S. in Computer Science Los Angeles, CA · Sep 2014 - Jun 2018

Staff ML Engineer Resume Example

Years of experience
11 years
Industry
GPU and foundation models
Stack
PythonPyTorchvLLMKubernetes
Download as PDF

Click to download the Staff ML Engineer resume example as a PDF. Free / No signup.

Adrián Schmidt

Staff ML Engineer

Santa Clara, CA · adrian.schmidt@gmail.com · +1 408-555-0119 · linkedin.com/in/adrianschmidt

Profile Summary
  • Staff ML Engineer with 11 years leading large-scale training and inference programs across GPU, autonomous-vehicle, and foundation-model workloads, specializing in distributed training, inference-runtime performance, and ML platform governance.
  • Hands-on across primary language (Python), systems language (C++ with CUDA basics), training framework (PyTorch DDP and FSDP), inference runtime (TensorRT-LLM, vLLM, Triton), distributed compute (Ray and NCCL), and orchestration (Kubernetes with the NVIDIA GPU operator).
  • Deep expertise in multi-node H100 training, FSDP migration, continuous batching and paged attention, and KV-cache tuning, using RFC-driven design reviews and SLO-backed rollouts to ship inference that gets cheaper every quarter.
  • Partners with Research, Product, Hardware, and Finance on inference-cost roadmaps and capacity planning, briefing executives on 6-quarter cost-of-inference projections and owning the on-call rotation for 4 high-stakes services.
  • Tech lead of 7 ML engineers who set up the team's RFC governance (18 RFCs shipped), the inference-runtime onboarding curriculum, and the Inference Platform forum the wider org now runs on.
Technical Skills
Languages:
Python, C++ (CUDA basics), Bash, Rust (basics)
Distributed Training:
PyTorch DDP and FSDP, Megatron-LM, DeepSpeed, NCCL, Horovod, multi-node H100 clusters
Inference Runtime:
TensorRT-LLM, vLLM, Triton Inference Server, continuous batching, paged attention, KV-cache tuning, quantization
Orchestration:
Kubernetes (GKE), NVIDIA GPU operator, Ray, Slurm, Argo Workflows
ML Platform:
MLflow, Weights & Biases, model registry, RFC governance, on-call playbooks
Observability & Cost:
Prometheus, Grafana, DCGM GPU metrics, inference SLO dashboards, cost-of-inference reporting
Leadership:
tech lead of 7, hiring loops, architecture reviews, executive briefings

Adrián Schmidt

Page 2 of 2
Work Experience
NVIDIA Staff ML Engineer Santa Clara, CA · Mar 2021 - Present
  • Tech lead for the inference-runtime team of 7 engineers, owning the Triton and TensorRT-LLM stack that serves 6 production models at 22k QPS across internal and partner workloads.
  • Led the FSDP migration from legacy DDP across 4 training programs, unlocking multi-node H100 training at trillion-parameter scale and cutting per-step time by 34%.
  • Drove an inference-optimization program on 3 flagship models with paged attention, continuous batching, and KV-cache tuning in TensorRT-LLM, lifting throughput 52% and cutting p99 latency 38%.
  • Set up the team's RFC governance and chair the bi-weekly Inference Platform forum, shepherding 18 RFCs through review, including the org-wide vLLM evaluation and adoption plan.
  • Own the on-call rotation for 4 high-stakes inference services, from runbooks and post-incident reviews to SLO error-budget enforcement, holding 99.95% availability for 6 straight quarters.
Cruise Senior ML Engineer San Francisco, CA · Jul 2014 - Feb 2021
  • Owned the perception model training platform, building Horovod distributed training pipelines for 12 perception models across LiDAR, camera, and radar modalities.
  • Built the on-vehicle inference runtime on a custom GPU operator, serving 8 perception models at p99 latency under 25 ms on the compute budget of a single drive unit.
  • Led the Kubernetes training-cluster migration across 3 GPU pools, unlocking 4x training throughput and cutting per-experiment cost by 42%.
Education
ETH Zurich M.S. in Computer Science Zurich, Switzerland · Sep 2012 - Jun 2014
Universität Hamburg B.Sc. in Computer Science Hamburg, Germany · Sep 2009 - Jul 2012

Free resume review

A recruiter screen, but with feedback

You applied to hundreds of jobs: no result. Companies won’t give you feedback, so you’re stuck in a loop. Rejections will keep coming until you know what’s wrong.

Let’s break this cycle today!

I’ll screen your resume the same way I did at Google.

You’ll get:

  • Your resume sections and content scored.
  • A clear list of what to improve, why, and how.
  • Behind the scenes secrets on the screening process.

Section by section

Machine Learning Engineer sections at a glance

Let’s evaluate the ML Engineer resume template one section at a time: the job each part does, an example of it done well, and the reason a recruiter pays attention to it.

01Profile Summary

Machine Learning Engineer Profile Summary example

A recruiter going through a pile of resumes gives each one a few seconds. A Profile Summary is what makes the first review possible, by listing all key information at the top. For a Machine Learning Engineer, that means your main stack (Python, PyTorch, Ray), the engineering problems you’ve solved (recommendation systems, LLM fine-tuning, model serving), how you work with research and product teams, and the models you have actually shipped.

The complete method is in my article: How to write a profile summary.

Profile Summary Sample
  • Machine Learning Engineer with 8 years of experience across e-commerce and marketplace platforms in search ranking, personalization, and LLM-powered assistants, specializing in model serving, fine-tuning, and evaluation.
  • Hands-on across primary language (Python), training framework (PyTorch), model hub (Hugging Face), distributed compute (Ray and Spark), inference (vLLM and Triton), ML platform (MLflow and Kubeflow), and cloud (AWS SageMaker), with strong fundamentals in transformers, retrieval, and learning to rank.
  • Deep expertise in LoRA fine-tuning, RAG pipelines, offline and online evaluation, and inference optimization, using methodologies such as eval-gated releases and shadow deployments to ship models that hold their offline gains in production.
  • Works end to end with research scientists, product managers, data platform, and SRE inside a two-week release cycle, owning each model from training run to on-call, with a pragmatic, measure-first mindset.
  • Senior MLE who raises the bar on evaluation discipline and cost per inference through model reviews and mentoring, while owning the team’s model registry and release checklist.

02Role Profile Coverage

Machine Learning Engineer role profile coverage

Every MLE opening comes with a role profile: the core competencies (skills plus experience) the hiring manager wants covered, and recruiters check your resume against it line by line. Tick most of the boxes and you get the interview, so give each competency its own specific bullet point.

Here is what the role profile of a modern ML Engineer looks like, which is what I used when writing content for the resume example. FYI, the full reasoning behind role profile targeting is in the Machine Learning Engineer resume writing guide.

Role Profile Coverage
  • ML System Design & Architecture
  • Model Development & Training
  • Data Pipelines & Feature Stores
  • Model Deployment & Serving
  • MLOps, CI/CD & Experiment Tracking
  • Model Monitoring & Observability
  • Performance Optimization & Scalability
  • Evaluation, Testing & Responsible AI

03Bullet Points

A Machine Learning Engineer resume bullet point example

Bullet points are where a resume is won or lost. A strong MLE bullet says which tools were involved (PyTorch, Ray, vLLM), which techniques you applied (LoRA fine-tuning, two-tower retrieval, quantization), and what expertise made it work (recommendation systems, LLM evaluation, model serving).

Then you need to measure your impact, which is (ideally) one metric per bullet point. For a Machine Learning Engineer, that could be offline accuracy or nDCG, p99 inference latency, or GPU cost per 1,000 requests (check out the MLE metrics page for a list of metrics you can use).

The example below is built with my “Level System”, the bullet point writing method I apply to every resume I rewrite.

Bullet Point Sample

Rebuilt the product search ranker with a two-tower retrieval model and a fine-tuned cross-encoder reranker, trained in PyTorch on Ray and served on Triton, under eval-gated releases with a 4-week A/B test, lifting search conversion by 9%.

  1. 01 Task What you worked on
  2. 02 Techniques How you did it
  3. 03 Tools The stack you used
  4. 04 Method The method you followed
  5. 05 Metric The result, one number

04Technical Skills

Machine Learning Engineer technical skills section example

For our Machine Learning Engineer resume template, I default to the following categories: languages, deep learning frameworks, LLM tooling, data and feature pipelines, serving and inference, ML platform / MLOps, and evaluation. Of course, this is just an example: feel free to adjust it to your specific experience.

Here is a Technical Skills block done properly. When you need more keywords for your own version, the Machine Learning Engineer resume skills page has the full list.

Technical Skills Sample
Languages
Python, SQL, C++ (CUDA basics), Bash
Deep Learning
PyTorch, JAX, Hugging Face Transformers, two-tower and DLRM models, learning to rank
LLM Tooling
LoRA and QLoRA fine-tuning, RAG pipelines, LangChain, vector search (FAISS, Qdrant), prompt and eval datasets
Data & Features
Spark, Ray Data, Airflow, Feast feature store, BigQuery, Parquet
Serving & Inference
vLLM, Triton Inference Server, TensorRT-LLM, ONNX, quantization, continuous batching
ML Platform
MLflow, Weights & Biases, Kubeflow Pipelines, model registry, GitHub Actions, Docker, Kubernetes
Evaluation & Monitoring
Offline eval harnesses, A/B testing, LLM evals, drift monitoring, Prometheus, Grafana

Submit your resume for a free review!

MLE Template File, Format and Layout

Machine Learning Engineer template & layout

That covers what goes into the resume. The other half is the file itself: whether an ATS can read it, whether a recruiter can scan it in a few seconds, and which format you send it in.

01ATS Compliance

ATS compliance for your Machine Learning Engineer resume

Nobody at the company reads your resume first: an Applicant Tracking System does. It pulls the text apart, drops it into fields (title, company, dates, skills) and runs its filters on the result. If that step goes wrong, your MLE resume is out before a recruiter has seen it, which is why it needs to be “ATS Compliant” from the start. These parsers are simple programs that break on unusual layouts, so here are the 3 rules I give every client.

The 3 rules
  1. Use a 100% text based format (no Canva!)

  2. Avoid tables, pictures, and complex structures.

  3. Choose the most predictable section names (“Profile Summary” rather than “Career Highlights”)

02Design & Layout

Machine Learning Engineer resume design and layout

Let me be blunt: recruiters hate fancy designs. At Google I would sit down with a queue of 100 to 200 resumes and get through them in a single afternoon. Each one got a few seconds of my attention, and every unusual layout cost me some of those seconds working out where the experience section had gone.

So my advice is to be boring and predictable with your layout and put all your effort into the content. Nothing else ever changed my decision. That is the thinking behind the template on this page: plain structure, standard section order, no surprises.

Layout Spec
Columns
One. No sidebars, tables, columns, pictures or tabs.
Margins
0.7 in on all four sides
Body size
10 to 11 pt
Type
One family, weight for hierarchy
Length
One page under 5 years, two after
Section order
Summary, Skills, Experience, Education
PDF

03File Format

Resume file format for your Machine Learning Engineer (MLE) resume

Always send a PDF. It is the format every ATS parses best, while .docx and .pages files get read less reliably and can reflow on another machine. A PDF also locks your layout, so what the recruiter opens is exactly what you exported (the download button on this template gives you one). I go through all the options in my resume file format article.

Format Guide
PDF
Your default. Layout holds, text stays selectable.
Word (.docx)
Only when the posting or the recruiter asks for it
Plain text
For portals that make you paste into a box
Never
Images, scans, Pages files, Google Docs links
File name
Priya-Nair-Machine-Learning-Engineer.pdf

Free resume review

A recruiter screen, but with feedback

You applied to hundreds of jobs: no result. Companies won’t give you feedback, so you’re stuck in a loop. Rejections will keep coming until you know what’s wrong.

Let’s break this cycle today!

I’ll screen your resume the same way I did at Google.

You’ll get:

  • Your resume sections and content scored.
  • A clear list of what to improve, why, and how.
  • Behind the scenes secrets on the screening process.

Frequently asked

Your Questions about the Machine Learning Engineer (MLE) Resume Template, Answered

Yes, no charge. No signup, no email required, no upgrade tier in the wings. Open it, fill in your details, save the PDF, and you're done.

Yes. The exported PDF is single-column with the section headers ATS systems read by default (Profile Summary, Technical Skills, Education, Work Experience), no tables, no images, no multi-column layouts. Workday, Greenhouse, and iCIMS handle it cleanly. Drop the export into our ATS Checker after if you want a second look.

You can. Toggle Edit at the top of the resume preview, then click into any sentence and rewrite it directly. The side-panel placeholders keep updating; the rest of the text is plain editable copy.

Hit Download. Your browser generates the PDF on the spot, no print dialog, no signup, no server in the loop. The output is real vector text on US Letter, parsed by ATS systems the same way they parse any clean resume export.

Yes. The defaults lean PyTorch + Hugging Face + LLM tooling because that's where 2026 ML Engineer JDs concentrate, but every reference is a placeholder. Swap PyTorch for TensorFlow or JAX, Hugging Face for native PyTorch, MLflow for Weights & Biases, Triton for SageMaker or Vertex AI, Feast for Tecton. The side panel updates the resume across every mention.

No. Hiring managers screen on substance: the systems you actually shipped, the models that moved a metric, the inference cost or latency wins you can defend in a screen, the evals and safety work you can talk through. Layout origin is not on the rubric. What does cost interviews is a template padded with vague ML-speak, which this one is structured to prevent. The skeleton came from a former Google recruiter; the substance is yours.

Yes, free. Drop your PDF into the review form on this page and a former Google recruiter (me) will read it and email back line-by-line notes inside 12 hours. No upsell, no hidden fee.

More resources

Other ML Engineer Resume Resources